LKA: Large-kernel Attention for Efficient and Robust Brain Lesion Segmentation
Medical Imaging meets NeurIPS 2023 Workshop.
Abstract. Vision transformers are effective deep learning models for vision tasks, including medical image segmentation. However, they lack efficiency and translational invariance, unlike convolutional neural networks (CNNs). To model long-range interactions in 3D brain lesion segmentation, we propose an all-convolutional transformer block variant of the U-Net architecture. We demonstrate that our model provides the greatest compromise in three factors: performance competitive with the state-of-the-art; parameter efficiency of a CNN; and the favourable inductive biases of a transformer. Our public implementation is available at https://github.com/liamchalcroft/MDUNet.
Year 2023Kind workshop paperVenue Medical Imaging meets NeurIPS 2023 Workshop
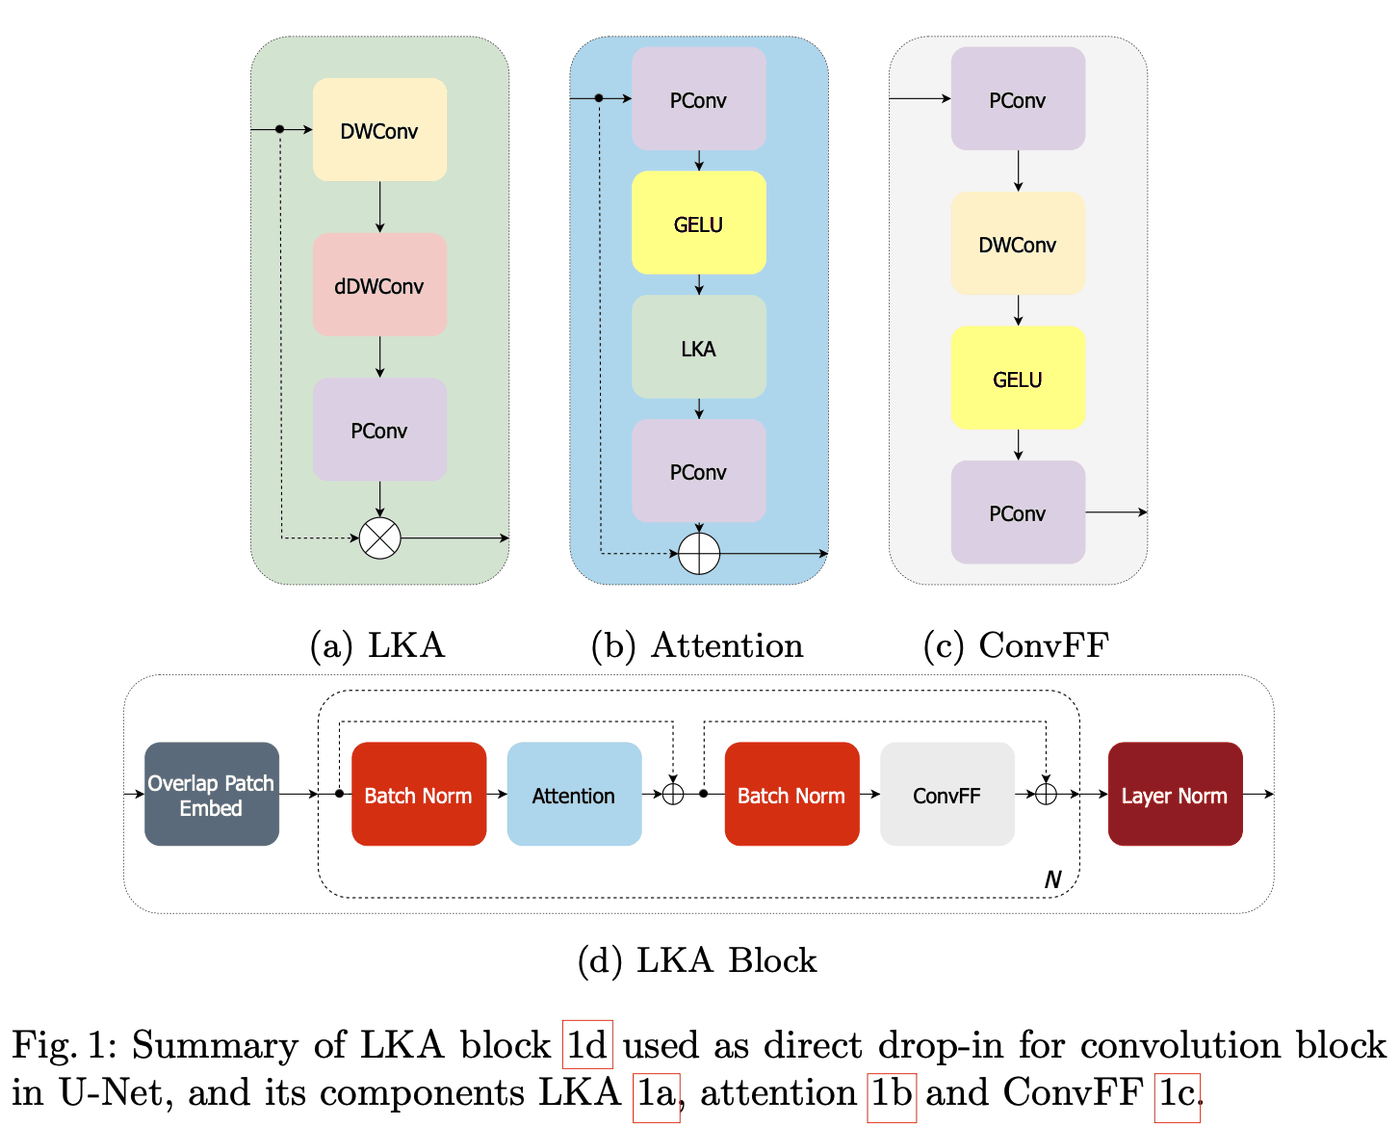
Figure 1 from the author preprint (arXiv v1): components of the large-kernel attention block and their placement within the architecture.
Materials
The MDUNet repository contains the convolutional attention architecture studied in this paper.
Architecture and evaluation details, including the original block diagram shown here.
@inproceedings{chalcroft2023lka,
  author    = {Chalcroft, Liam and Pereira, Ruben Lourenço and Brudfors, Mikael and Kayser, Andrew S. and D'Esposito, Mark and Price, Cathy J. and Pappas, Ioannis and Ashburner, John},
  title     = {{LKA: Large-kernel Attention for Efficient and Robust Brain Lesion Segmentation}},
  booktitle = {Medical Imaging meets NeurIPS 2023 Workshop},
  year      = {2023},
  url       = {https://arxiv.org/abs/2308.07251}
}